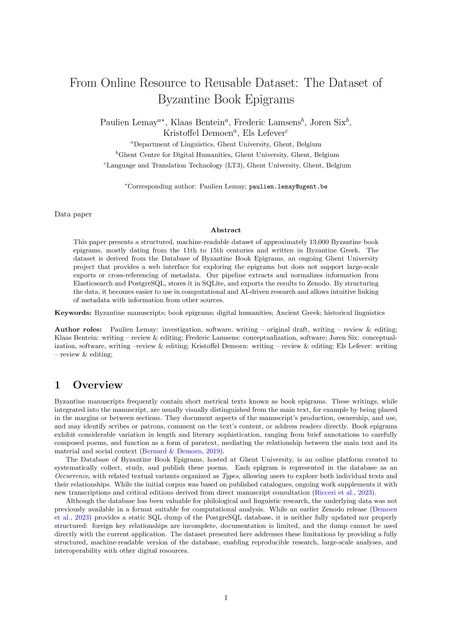
From Online Resource to Reusable Dataset: The Dataset of Byzantine Book Epigrams
Journal of Open Humanities Data
I have profiles on UGent Biblio, Google Scholar, ResearchGate, Research Portal Flanders, and UGent Research. However, this page is the most complete and regularly updated source for my publications. The full list can be found below.
Journal of Open Humanities Data
Posters, Demos, Blue Sky, and Tutorials at SEMANTiCS 2026
Posters, Demos, Blue Sky, and Tutorials at SEMANTICS 2026
Journal of Open Source Software
European Journal of Neuroscience,
Advances in Speech and Music Technology
Late Breaking Demo session of the 22st International Society for Music Information Retrieval Conference - ISMIR 2021
ISMIR 2022 Late Breaking / Demo abstracts
Journal of Open Source Software
Annals of the New York Academy of Science
Annals of the New York Academy of Science
ISMIR 2020 Late Breaking / Demo abstracts
Gériatrie et Psychologie Neuropsychiatrie du Vieillissement.
Frontiers in Neuroscience
Proceedings of the 9th Folk Music Analysis (FMA) conference
Proceedings of the 9th Folk Music Analysis (FMA) conference
Journal on Multimodal User Interfaces
Extended abstracts for the Late-Breaking Demo Session of the 19th International Society for Music Information
Critical Arts South-North Cultural and Media Studies
Proceedings of the 14th Italian Research Conference on Digital Libraries (IRCDL 2018)
Proceedings on the 42nd American of Biomechanics Congress.
Transactions of the International Society of Music Information Retrieval
Journal of New Music Research, Special edition on Digital Philology
Proceedings of AES Conference on Semantic Audio
Proceedings of the ESCOM conference
Proceedings of the 4th International Digital Libraries for Musicology workshop (DLfM 2017)
Proceedings of the 4th International Digital Libraries for Musicology workshop (DLfM 2017)
Physics in Medicine
Proceedings of the 5th Folk Music Analysis (FMA) conference
Journal on Multimodal User Interfaces
Proceedings of the Audio Engineering Society Conference: 53rd International Conference: Semantic Audio
Proceedings of the 15th ISMIR Conference (ISMIR 2014)
Journal of New Music Research
Journal of New Music Research. 42(2)
Proceedings of the 12th International Symposium on Music Information Retrieval
Demo Sessions of the 12th International Society for Music Information Retrieval Conference (ISMIR 2011)
Panel discussion, 2012: Technological challenges for the computational modelling of the world’s musical heritage, Folk Music Analysis Conference 2012 – FMA 2012, organizers: Polina Proutskova and Emilia Gomez, Seville, Spain
Guest lecture, 2012: Non-western music and digital humanities, for: “Studies in Western Music History: Quantitative and Computational Approaches to Music History”, M.I.T., Boston, U.S.
Guest lecture, 2011: Presenting Tarsos, a software platform for pitch analysis. At: Electrical and Electronics Eng.Dept. IYTE, Izmir, Turkey
Workshop 2017:Computational Ethnomusicology – Methodologies for a new field Leiden, The Netherlands
A002301 (2016-2017) “Grondslagen van de muzikale acoustica en sonologie” – Theory and Practice sessions together with dr. Pieter-Jan Maes
I am recognized as co-inventor on a Patent titled Low impact running WO/2020/002275
For research software see the software output page
The SEMANTiCS conference took place in Ghent from 15 to 17 September 2026. Our contribution was a collaboration between GhentCDH and the Semantic Computing Research Group at Aalto University on publishing humanities data with Sampo-UI and Ontop.
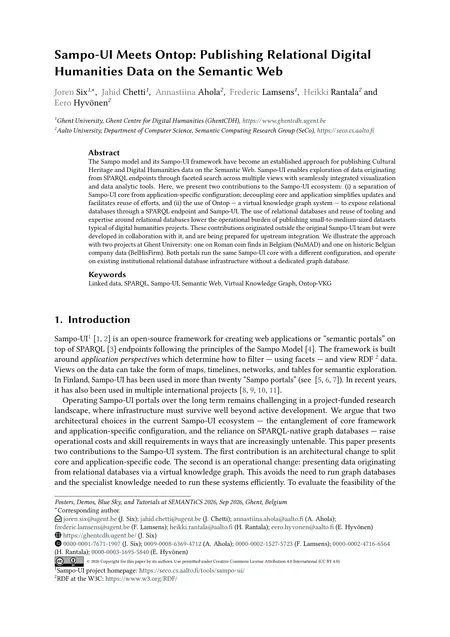
Sampo-UI Meets Ontop: Publishing Relational Digital Humanities Data on the Semantic Web, Joren Six¹, Jahid Chetti¹, Annastiina Ahola², Frederic Lamsens¹, Heikki Rantala², Eero Hyvönen²
¹ Ghent University, Ghent Centre for Digital Humanities (GhentCDH)
² Aalto University, Department of Computer Science, Semantic Computing Research Group (SeCo)
At GhentCDH, we often publish research datasets in the digital humanities. Several projects need similar search filters, map visualizations and data exports. Sampo-UI makes it possible to reuse these components when the data is available as Linked Data. In collaboration with the original Sampo-UI team, we worked on modernizing the framework. Our first contribution separates the shared core from project-specific configuration, making updates and reuse more manageable. The second uses Ontop to expose existing relational databases through a SPARQL endpoint. This lets us use Sampo-UI while keeping the database infrastructure and tooling we already have. Having one fewer database system to maintain is welcome.
Abstract: The Sampo model and its Sampo-UI framework have become an established approach for publishing Cultural Heritage and Digital Humanities data on the Semantic Web. Sampo-UI enables exploration of data originating from SPARQL endpoints through faceted search across multiple views with seamlessly integrated visualization and data analytic tools. Here, we present two contributions to the Sampo-UI ecosystem: (i) a separation of Sampo-UI core from application-specific configuration; decoupling core and application simplifies updates and facilitates reuse of efforts, and (ii) the use of Ontop — a virtual knowledge graph system — to expose relational databases through a SPARQL endpoint and Sampo-UI. The use of relational databases and reuse of tooling and expertise around relational databases lower the operational burden of publishing small-to-medium-sized datasets typical of digital humanities projects. These contributions originated outside the original Sampo-UI team but were developed in collaboration with it, and are being prepared for upstream integration. We illustrate the approach with two projects at Ghent University: one on Roman coin finds in Belgium (NuMAD) and one on historic Belgian company data (BelHisFirm). Both portals run the same Sampo-UI core with a different configuration, and operate on existing institutional relational database infrastructure without a dedicated graph database.
The demo below shows the NuMAD portal for exploring Roman coin finds in Belgium through the modernized Sampo-UI. Another demo presents historical records of Belgian companies through the BelHisFirm portal. Both portals run the same Sampo-UI core with different configurations, demonstrating the flexibility of the system.
Alongside the Sampo-UI Meets Ontop paper, a conference poster on Sampo-UI that I prepared is also available.
Video: NuMAD — exploring Roman coin finds in Belgium.
 UGent, Code, Presentation, and GhentCDH
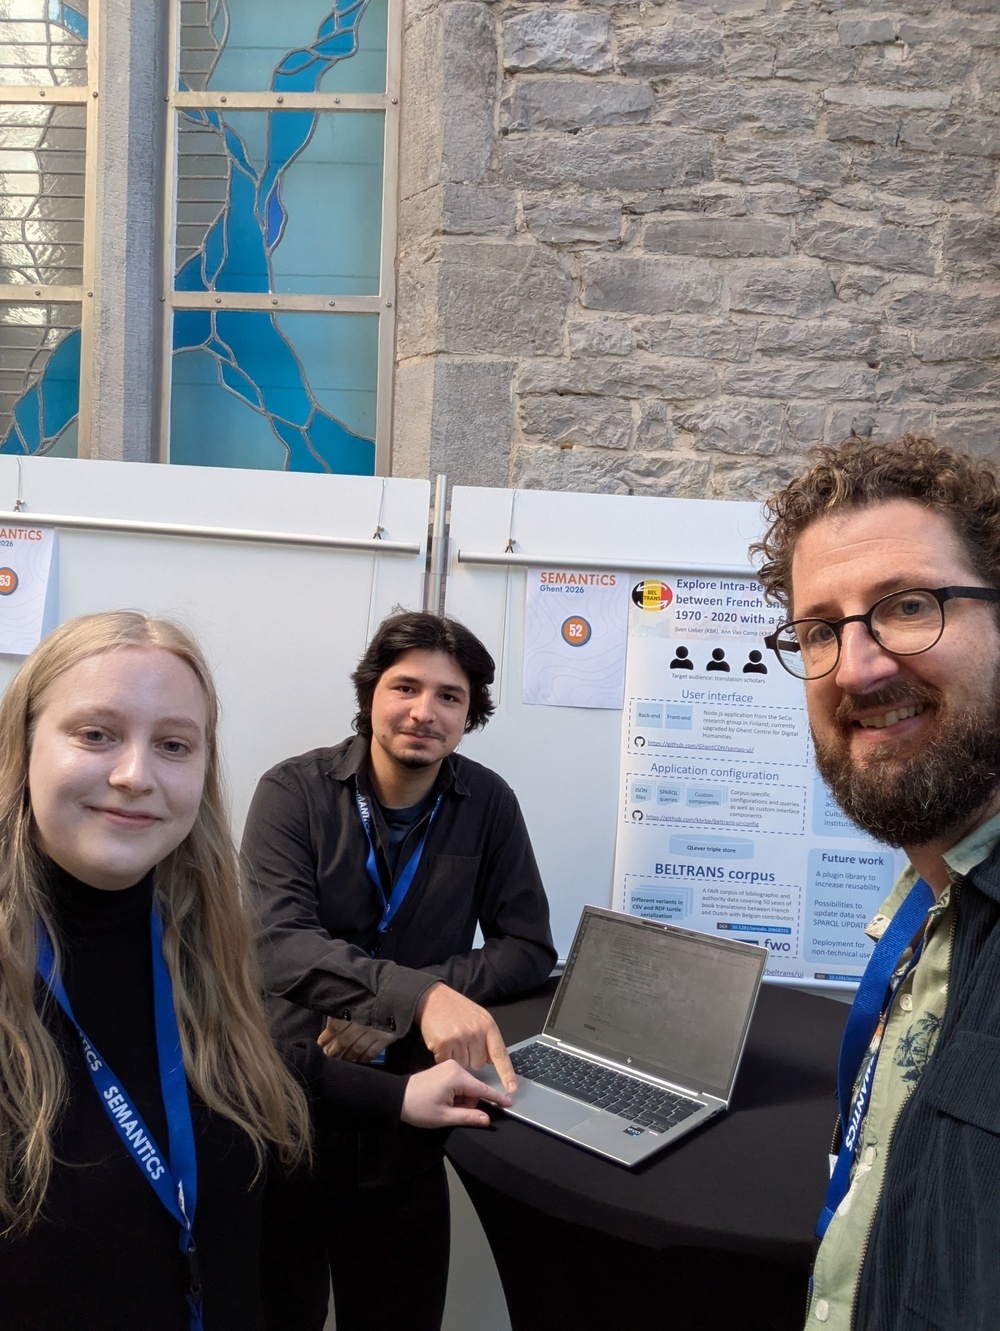
Another contribution presented at the SEMANTiCS conference in Ghent was a Sampo-UI portal for the BELTRANS project. I made a small contribution to the software and the paper, working with colleagues at KBR, the Royal Library of Belgium.
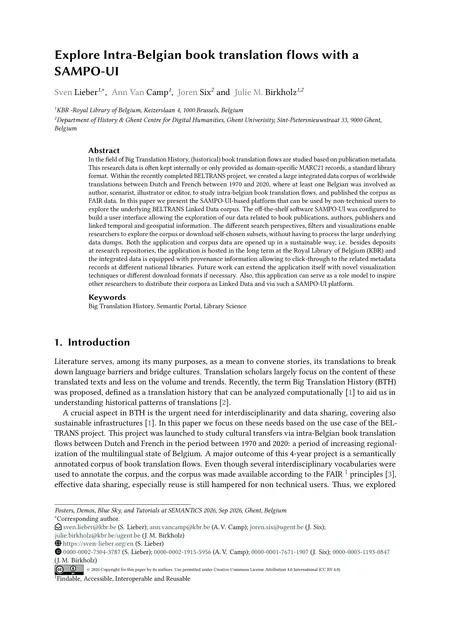
Explore Intra-Belgian book translation flows with a SAMPO-UI, Sven Lieber¹, Ann Van Camp¹, Joren Six², Julie M. Birkholz¹ ²
¹ KBR — Royal Library of Belgium
² Ghent University, Department of History & Ghent Centre for Digital Humanities
The BELTRANS project studied book translations between Dutch and French from 1970 to 2020, involving at least one Belgian author, scenarist, illustrator or editor. The resulting dataset brings together publication metadata from different libraries. Making these data available is one thing; making them easy to explore is another.
The BELTRANS portal uses Sampo-UI to let researchers filter publications, browse authors and publishers, explore maps and download selected data as CSV. It uses the modernized Sampo-UI core described in my Sampo-UI Meets Ontop post. Here, the data are served by QLever, a graph database with a SPARQL endpoint. The same interface components find another use, this time for translation history.
Abstract: In the field of Big Translation History, (historical) book translation flows are studied based on publication metadata. This research data is often kept internally or only provided as domain-specific MARC21 records, a standard library format. Within the recently completed BELTRANS project, we created a large integrated data corpus of worldwide translations between Dutch and French between 1970 and 2020, where at least one Belgian was involved as author, scenarist, illustrator or editor, to study intra-belgian book translation flows, and published the corpus as FAIR data. In this paper we present the SAMPO-UI-based platform that can be used by non-technical users to explore the underlying BELTRANS Linked Data corpus. The off-the-shelf software SAMPO-UI was configured to build a user interface allowing the exploration of our data related to book publications, authors, publishers and linked temporal and geospatial information. The different search perspectives, filters and visualizations enable researchers to explore the corpus or download self-chosen subsets, without having to process the large underlying data dumps. Both the application and corpus data are opened up in a sustainable way, i.e. besides deposits at research repositories, the application is hosted in the long term at the Royal Library of Belgium (KBR) and the integrated data is equipped with provenance information allowing to click-through to the related metadata records at different national libraries. Future work can extend the application itself with novel visualization techniques or different download formats if necessary. Also, this application can serve as a role model to inspire other researchers to distribute their corpora as Linked Data and via such a SAMPO-UI platform.
The BELTRANS corpus and the portal configuration are available for reuse.
UGent, Presentation, Research papers, and Projecten
Sampo-UI 4 was officially released at the SEMANTiCS conference in Ghent. Together with Jahid Chetti, Heikki, Annastiina Ahola and Frederic Lamsens, we worked on bringing the GhentCDH fork back into the main Sampo-UI repository.
The release includes an updated software stack, a clearer separation between the shared core and project-specific configuration, and a new plug-in system. These changes make it easier to reuse components across projects and keep portals up to date.
The GhentCDH fork has now been merged upstream. Our work continues as part of the shared Sampo-UI project, in collaboration with the original SeCo team.
For more on the changes and their use in our projects, see Sampo-UI Meets Ontop. ```
 UGent and Presentation
FedOSC, the Belgian Federal Open Science Cloud, supports open science and research data management at Belgium’s federal scientific institutions. On 8 September 2026, it organised a day on data visualisation and Linked Open Data at KIK-IRPA in Brussels, with talks, demos and a approaches on cultural heritage datasets.
My contribution to the closing talks was an introduction to Sampo-UI, an open-source framework for building search and visualisation interfaces on top of Linked Open Data. I explained why we use it at the Ghent Centre for Digital Humanities: several projects need similar filters, maps and data exports, so it makes sense to reuse a common framework. The presentation covers how Sampo-UI works, our contributions to it, and a practical example with the NuMAD coin database.
The Sampo-UI presentation is available online and embedded below.
UGent, Presentation, and GhentCDH
This morning I gave a guest lecture introducing the field of music information retrieval to musicology students at Ghent University. Next to the more general MIR intro, two specific topics are fleshed out: duplicate detection and pitch patterns in music around the world. Two topic I have been working on before.
The presentation has the form of an interactive website via reveal.js. It features a couple of slides which are full-blown applications or have an interactive sound visualization component. Please do try out the slides and check the Music Information Retrieval - Opportunities for digital musicology presentation or try it below.
UGent and Presentation
 MIR_intro.pdf
The research day of the faculty of Arts and Philosophy of Ghent University took place last November. The theme of the day was ‘From Source to Understanding’ and the program gave an overview of the breadth of research at our faculty with topics as logic, history, archeology, chemistry, geography, language studies, … There were several contributions by our group: the Ghent Center for Digital Humanities. The contribution by me and my close colleagues was a poster about a reusable text annotation building block.
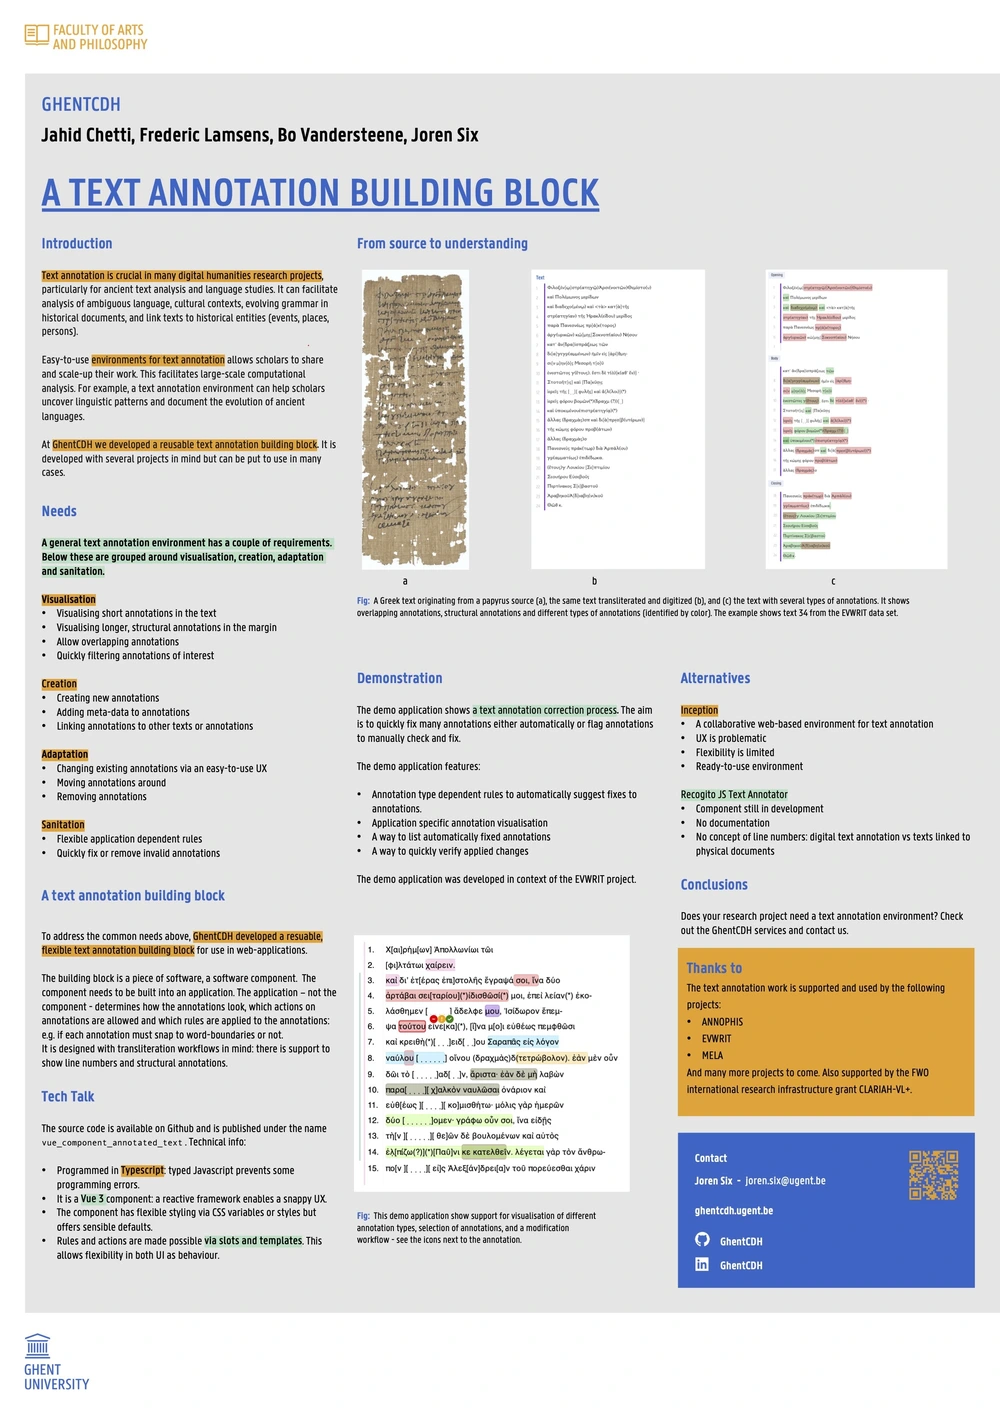
At GhentCDH we support several text annotation projects and have extracted a text annotation component for reuse. The abstract reads:
“Text annotation is essential for analyzing ancient texts, identifying entities in texts, or documenting evolving grammar. There is a need for reusable annotation methods which copes with challenges such as overlapping annotations, filtering annotation types, and enabling large-scale collaboration and computational analysis on text annotation work.
We present a reusable text annotation component built with TypeScript and Vue 3. It provides an intuitive interface for creating, visualizing, and editing annotations, it allows component users to enrich annotations with complex metadata, and facilitates flexible annotation filtering. This solution meets many needs of researchers in digital humanities and ancient language studies and will be used in several GhentCDH projects.”
Get more info, try it out and use it in your project by checking the text annotator source code repository.
UGent, Presentation, and GhentCDH
The publication of this paper seemed an almost sisyphean task, but it is now finally in print after about four years since first submission. All’s well that ends well and it is well indeed: the paper contributes a fundamental insight around the resultant peak tibial acceleration (PTA) in forefoot running: contrary to what is often presumed, the resultant PTA is higher in forefoot running! The paper combines two separate experiments into a single analysis framework which ensures robustness in the finding. The conclusions of the article can be found below:
Conclusions Many coaches and practitioners presume that forefoot striking decreases impact severity and prevents overuse injuries; however, our data show that instructed and habitual forefoot strikes have greater resultant but not axial PTA than habitual rearfoot strikes in level running at a submaximal speed. The forefoot strikes had a sharp decrease in the antero-posterior velocity of the shank following touchdown and, therefore, a greater antero-posterior acceleration, which resulted in the greater resultant peak tibial acceleration compared to the rearfoot strikes. Conclusively, the foot strike pattern differently affected PTAs and should be taken into account when evaluating 3D impact severity in distance runners.
My contribution to the paper was limited to technical development and support during the measurements at Ghent University. For the full paper, please read the publishers version of Validity and reliability of peak tibial accelerations as real-time measure of impact loading during over-ground rearfoot running at different speeds.
UGent and Research papers
 Fig: Some AI imagining audio search.
Recently I have published a paper titled ‘Olaf: a lightweight, portable audio search system’ in the Journal of Open Source Software (JOSS). The journal is a ‘hack’ to circumvent the focus on citable papers in the academic world: getting recognition for publishing software as a researcher is not straightforward.
Both Ghent University’s research output tracking system and Flanders FWO academic profile do not allow to enter software as research output. The focus is still solely on papers, even when custom developed research software has become a fundamental aspect in many research areas. My role is somewhere between that of a ‘pure’ researcher and that of a research software engineer which makes this focus on papers quite relevant to me.
The paper aims to make the recent development on Olaf ‘count’. Thanks to the JOSS review process the Olaf software was improved considerably: CI, unit tests, documentation, containerization,… The paper was a good reason to improve on all these areas which are all too easy to neglect. The paper itself is a short, rather general overview of Olaf:
“Olaf stands for Overly Lightweight Acoustic Fingerprinting and solves the problem of finding short audio fragments in large digital audio archives. The content-based audio search algorithm implemented in Olaf can identify a short audio query in a large database of thousands of hours of audio using an acoustic fingerprinting technique.”
Command Line Application, Music Information Retrieval, Research papers, and UGent
I have recently published an chapter in an academic book published by Springer. The topic of the book is of interest to me but can be perceived as rather dry: Advances in Speech and Music Technology.
The chapter I co-authored presented two case studies on detecting duplicates in music archives. The fist case study deals with segmentation reuse in an archive of early electronic music. The second with meta-data reuse in an archive of a public broadcaster containing digitized commercial shellac disc recordings with many duplicates.
Duplicate detection being the main topic, I decided to title the article Duplicate Detection for for Digital Audio Archive Management. It is easy to miss, and not much is lost if you do, but there is a duplicate‘for’ in the title. If you did detect the duplicate you have detected the duplicate in the duplicate detection article. Since I have fathered two kids I see it as an hard earned right to make dad-jokes like that. Even in academic writing.
It was surprisingly difficult to get the title published as-is. At every step of the academic publishing process (review, editorial, typesetting, lay-outing) I was asked about it and had to send an email like the one below. Every email and every explanation made my second-guess my sense of humor but I do stand by it.
From: Joren
\ To: Editors ASMT
\
\ Dear Editors,
\
\ I have updated my submission on easychair in...\
\ I would like to keep the title however as is an attempt at word-play. These things tend to have less impact when explained but the article is about duplicate detection and is titled 'Duplicate detection for for digital audio archive management'. The reviewer, attentively, detected the duplicate 'for' but unfortunately failed to see my attempt at humor. To me, it is a rather harmless witticism. Regards Joren </pre>
Anyway, I do think that humor can serve as a gateway to direct attention to rather dry, academic material. Also the message and the form of the message should not be confused. John Oliver, for example, made his whole career on delivering serious sometimes dry messages with heaps of humor: which does not make the topics less serious. I think there are a couple of things to be learned there. Anyway, now that I have your attention, please do read the author version of Duplicate Detection for for Digital Audio Archive Management: Two Case Studies.
Poging tot humor, Research papers, and UGent
 Fig: DALL.E 2 imagining a fight between papers and software.
Recently I have published a paper titled ‘Panako: a scalable audio search system’ in the Journal of Open Source Software (JOSS). The journal is a ‘hack’ to circumvent the focus on citable papers in the academic world: getting recognition for publishing software as a researcher is not straightforward.
The research output tracking system of Ghent University (biblio) and Flanders FWO’s academic profile are not built to track software as research output. The focus is still solely on papers, even when custom developed research software has become a fundamental aspect in many research areas. My role is somewhere between that of a ‘pure’ researcher and that of a research software engineer which makes this focus on papers quite relevant to me.
The paper aims to make the recent development on Panako ‘count’. Thanks to the JOSS review process the Panako software was improved considerably: CI, unit tests, documentation, containerization,… The paper was a good reason to improve on all these areas which are all too easy to neglect. The paper itself is a short, rather general overview of Panako:
“Panako solves the problem of finding short audio fragments in large digital audio archives. The content based audio search algorithm implemented in Panako is able to identify a short audio query in a large database of thousands of hours of audio using an acoustic fingerprinting technique.”
UGent, Panako, and Research papers
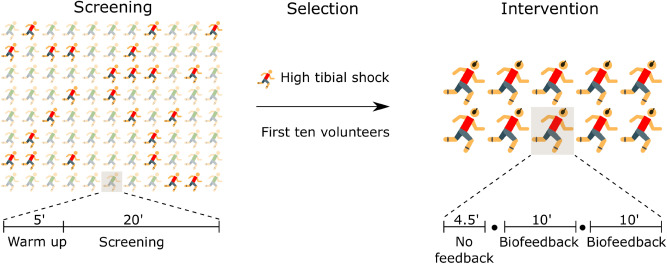
I have been lucky to have been involved in an interdisciplinary research project around the low impact runner: a music based bio-feedback system to reduce tibial shock in over-ground running. In the beginning of October 2022 the PhD defence of Rud Derie takes place so it is a good moment to look back to this collaboration between several branches of Ghent University: IPEM , movement and sports science and IDLab.
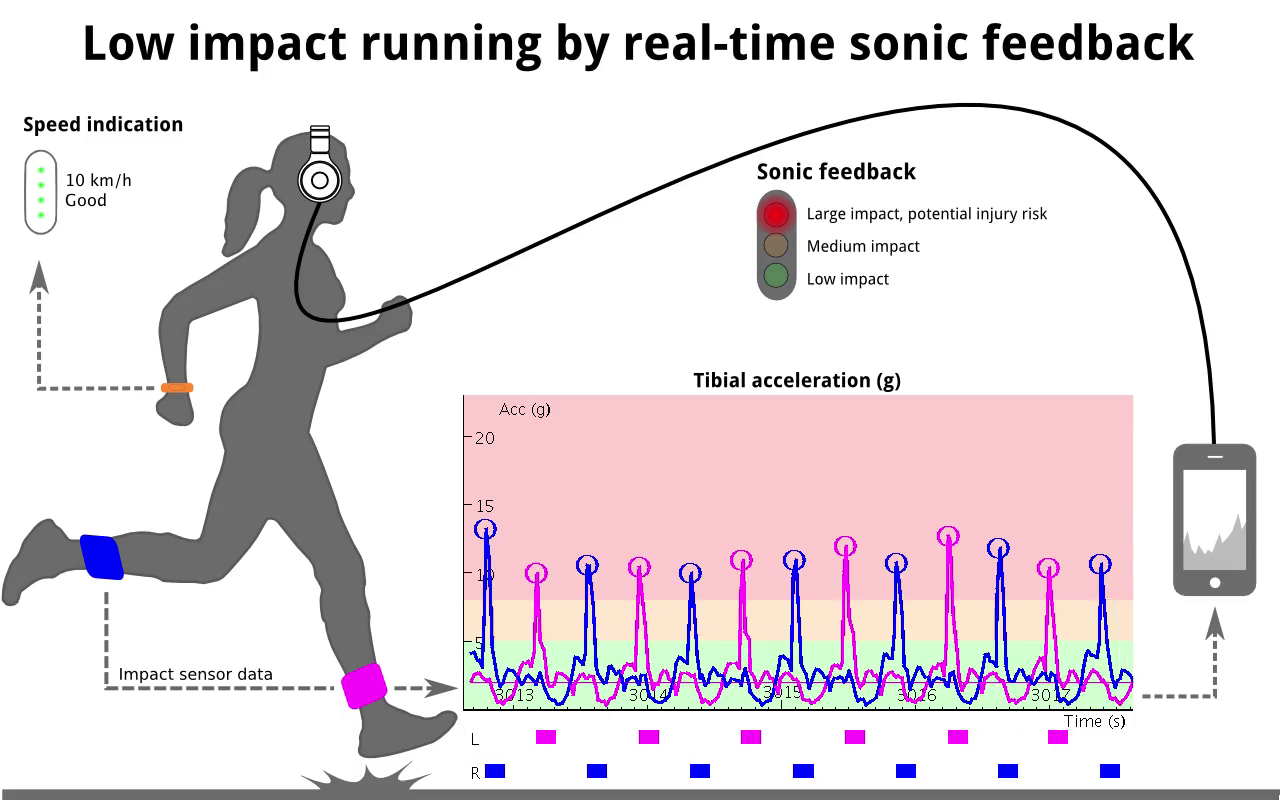
The idea behind the project was to first select runners with a high foot-fall impact. Then an intervention would slightly nudge these runner to a running style with lower impact. A lower repetitive impact is expected to reduce the chance on injuries common for runners. A system was invented in which musical bio-feedback was given on the measured impact. The schema to the right shows the concept.
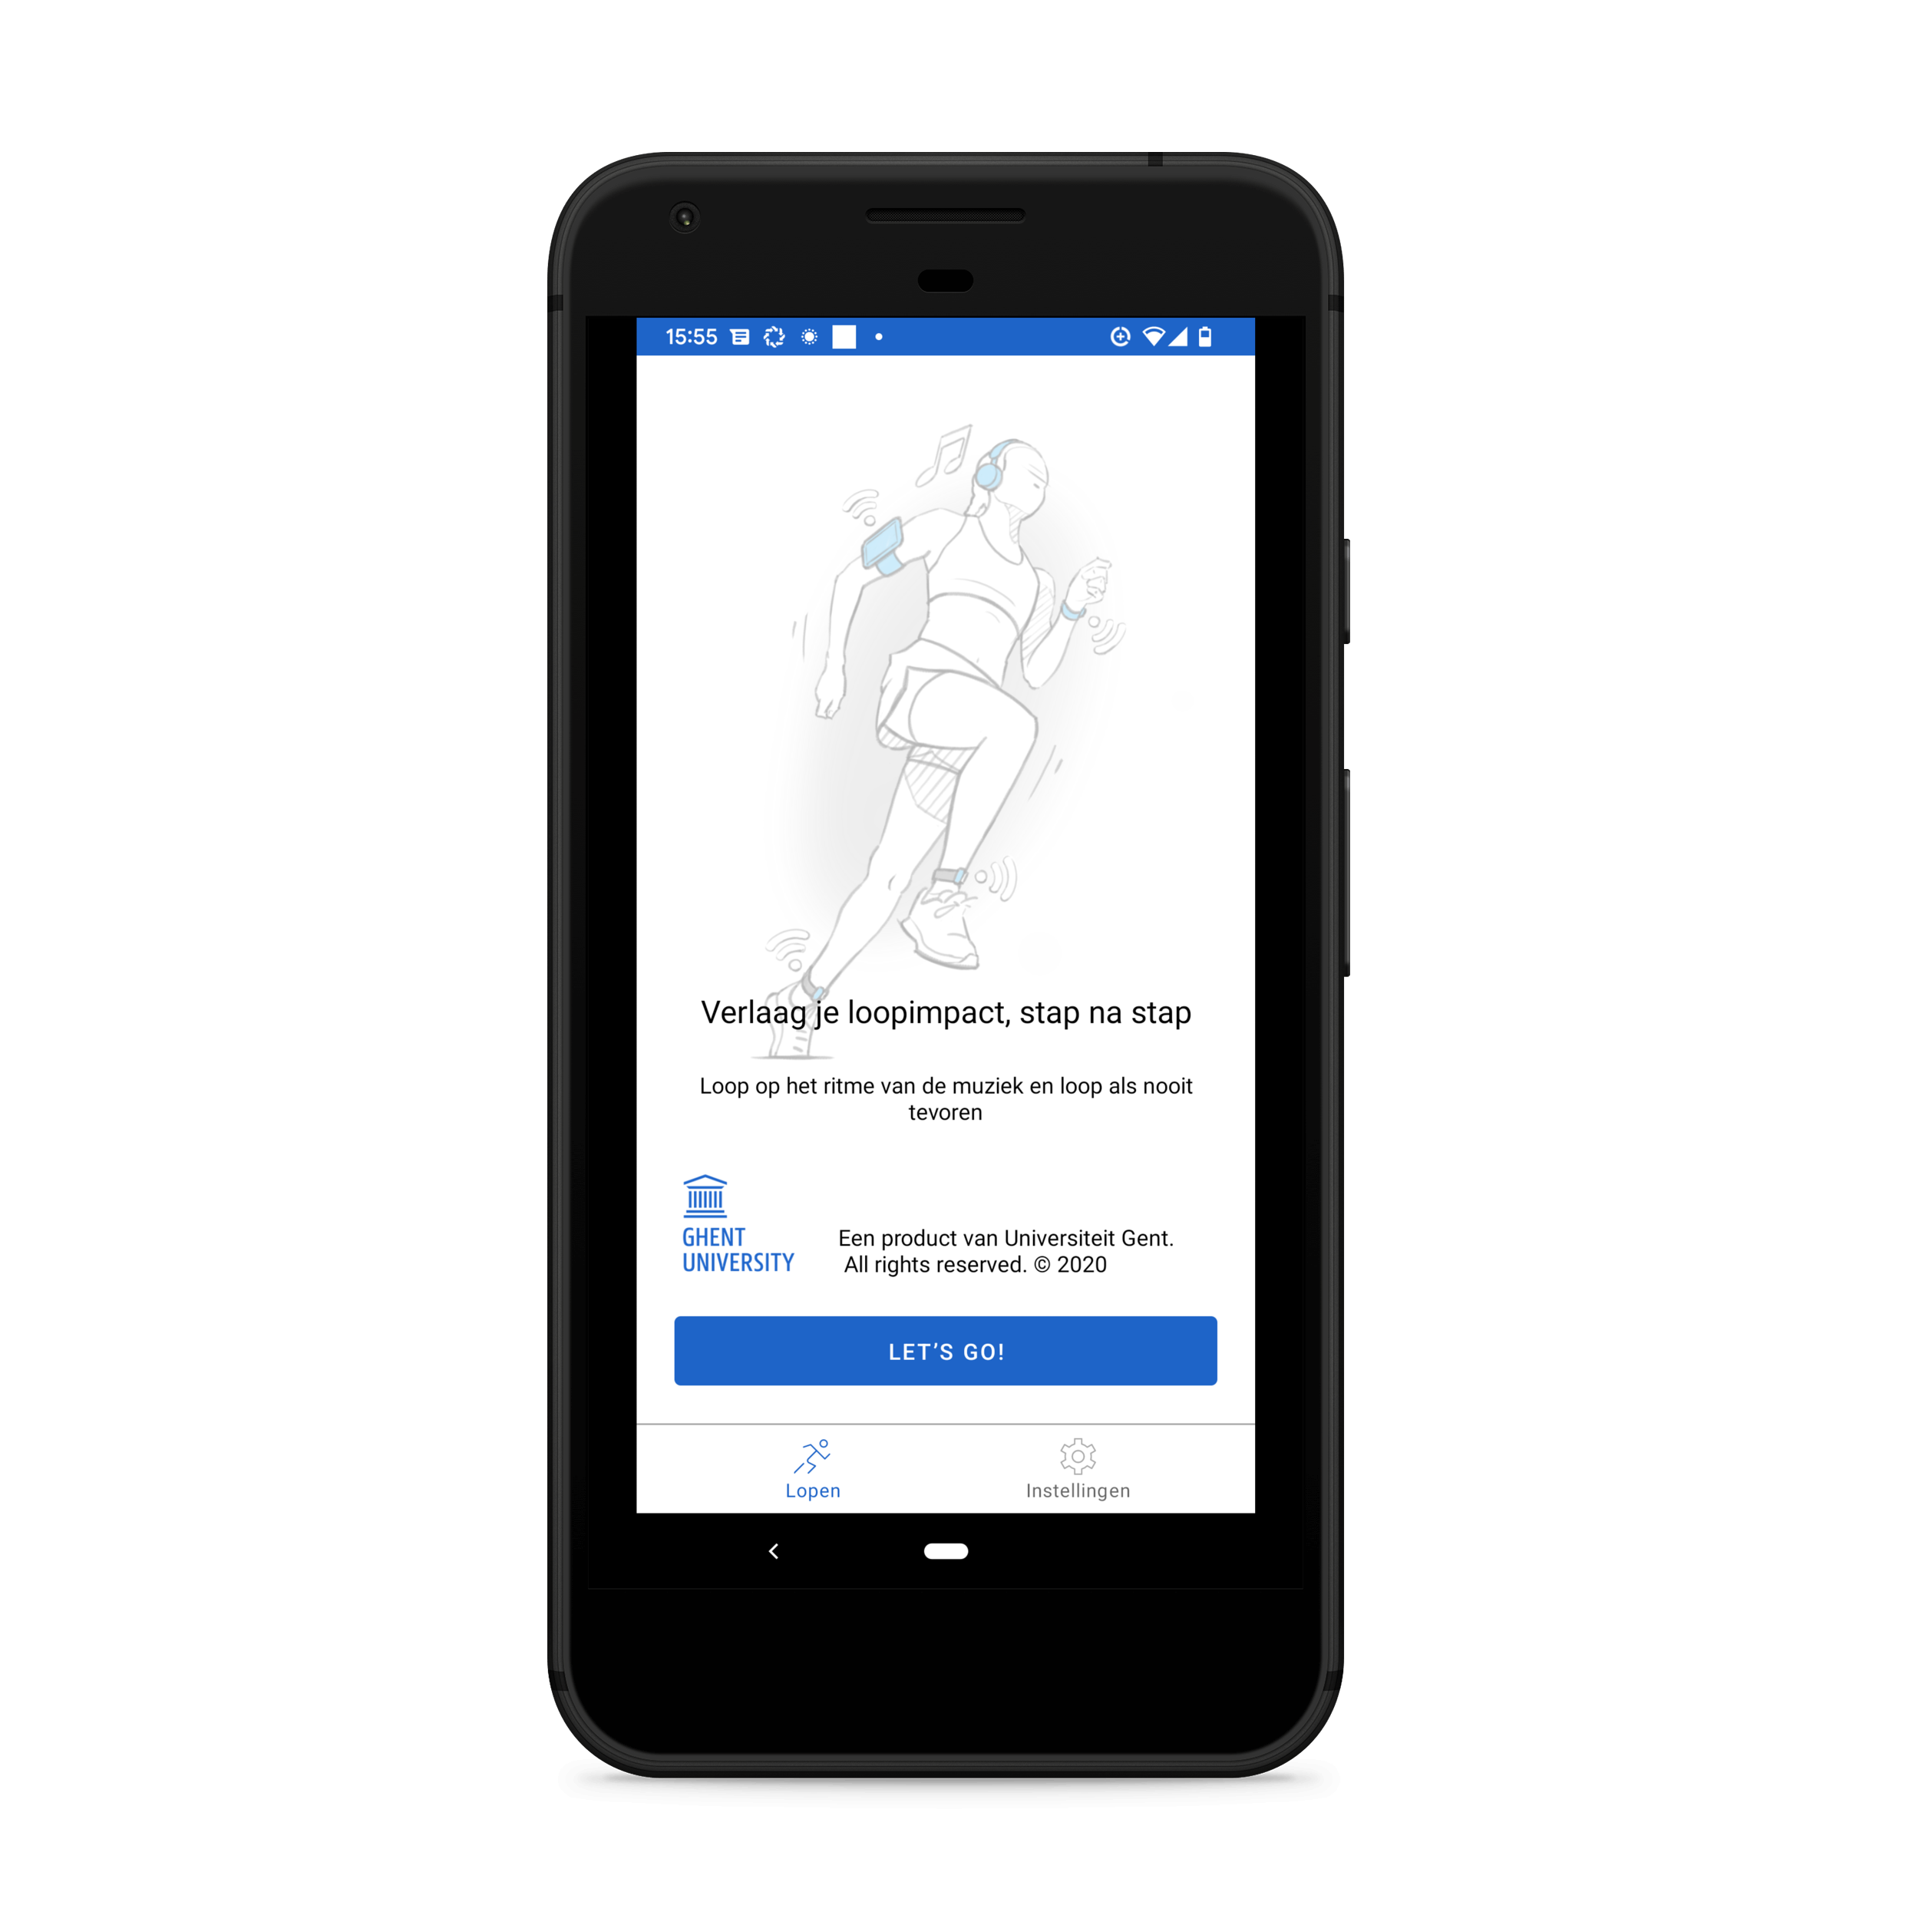
I was involved in development of the first hardware prototypes which measured acceleration on the legs of the runner and the development of software to receive and handle these measurement on a tablet strapped to a backpack the runner was wearing. This software also logged measurements, had real-time visualisation capabilities and allowed remote control and monitoring over the network. Finally measurements were send to a Max/MSP sonification engine. These prototypes of software and hardware were replaced during a valorization project but some parts of the software ended up in the final Android application.
Over time the first wired sensors were replaced with wireless Bluetooth versions. This made the sensors easy to use and also to visualize sensor values in the browser thanks to the Web Bluetooth API. I have experimented with this and made two demos: a low impact runner visualizer and one with the conceptual schema.
The following three studies shows a part of the trajectory of the project. The first paper is a validation of the measurement system. Secondly a proof-of-concept study is done which finally greenlights a larger scale intervention study.
Van den Berghe, P., Six, J., Gerlo, J., Leman, M., & De Clercq, D. (2019). Validity and reliability of peak tibial accelerations as real-time measure of impact loading during over-ground rearfoot running at different speeds. Journal of Biomechanics, 86, 238-242.
Van den Berghe, P., Lorenzoni, V., Derie, R., Six, J., Gerlo, J., Leman, M., & De Clercq, D. (2021). Music-based biofeedback to reduce tibial shock in over-ground running: A proof-of-concept study. Scientific reports, 11(1), 1-12.
Van den Berghe, P., Derie, R., Bauwens, P., Gerlo, J., Segers, V., Leman, M., & De Clercq, D. (2022). Reducing the peak tibial acceleration of running by music‐based biofeedback: A quasi‐randomized controlled trial. Scandinavian Journal of Medicine & Science in Sports
There are quite a number of other papers but I was less involved in those. The project also resulted in two PhD’s:
I am also recognized as co-inventor on the low impact runner system patent and there are concrete plans for a commercial spin-off. To be continued…

 UGent, IPEM, Java, and Research papers